Read 50 published accounts of agentic AI in production and a pattern emerges fast. Escalations down. Handling times down. Conversion up. Onboarding compressed from weeks to days.
Now read them looking for how those numbers were produced, and the field thins out. The window is rarely stated, the denominator almost never and concurrent initiatives that could have produced the same movement go unnamed. You get a number and an implied causal claim, with nothing a skeptic could object to.
This usually isn’t dishonesty. Nobody has told practitioners what a defensible result looks like, so careful and careless accounts read identically.
The cost lands on CIOs. If you’re weighing a major agentic investment, you can’t tell a result achieved at peak trading volume from one achieved in a quiet quarter with the window picked afterward. Both show up as a percentage.
I recently completed an 18-month deployment of 25 production agents across a large travel and cruise group. I’ve written about the strategy and the domain-tuned small models behind it, but not how far its numbers can be trusted. Here is the standard I now hold them to, and the operational failure that undermines every metric if you miss it.
Five ways deployments corrupt their own measurement
- The denominator moves. An agent reduces escalations. So does a quiet quarter. A rate without its volume is a way of declining to say which happened.
- The window is chosen after the fact. A steadily improving agent always has some recent window in which it looks better than any earlier one, and research on analytical flexibility shows how easily that produces apparently strong findings from nothing. The tell: when one account reports three outcomes over three different periods, the periods were fitted to the outcomes.
- The baseline contains slack. Automate a manual process and you usually clear its backlog at the same time, so the comparison measures a faster process and a one-off vanished queue at once.
- The change is never alone. Organizations willing to deploy autonomous agents are usually already in motion: a platform rebuild, a repricing, a reorganization. Year-over-year comparison controls for seasonality, and for none of that.
- The definition is proprietary. A “Tier 1 escalation” in your own platform means whatever your queue classification says, and isn’t comparable with a competitor’s figure, though both appear as percentages.
CLEAR: Five tests for a reportable result
The NIST AI Risk Management Framework and ISO/IEC 42001 tell you to measure, not what a reportable number looks like. CLEAR sits beneath them and needs only ordinary operational records and one discipline: decide before you know the result.
- C: Concurrent changes registered. What else changed in the same window, and could it independently produce the result?
- L: Locked window. Was the period fixed before the result was known, and does it include your hardest trading conditions?
- E: Evidentiary custody. Which system produced the count, who defines the category and who reviewed the figure?
- A: Attributable baseline. How much of the gain came from re-engineering the process, and how much from clearing accumulated slack?
- R: Reference volume. Did the underlying volume hold steady, and is that stated?
Four tests ask for disclosure, which is cheap. The locked window asks for pre-commitment, which is costly because it forecloses discovering later that a different period tells a better story. In my experience, it does most of the work.
Medicine and ML research already have reporting standards such as CONSORT-AI and REFORMS; agentic deployments don’t. CLEAR isn’t a validity standard, though: a result that passes all five is still a single-organization observation. It gives you an account a skeptic can attack.
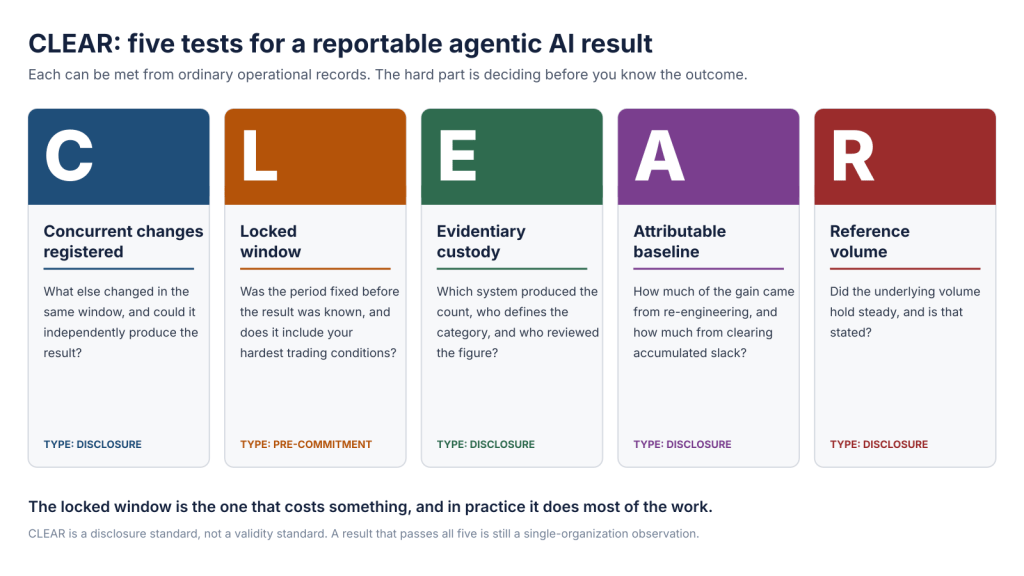
The CLEAR standard: Five tests for a reportable agentic AI result.
Naren Gangavarapu
Applying it to my own results
We used three outcomes internally to justify further investment. Two came out weaker under CLEAR.
Tier 1 support escalations fell 34%
This largely survives. The six-month window was fixed to include peak season, contact volume was flat year over year and counts came from the system of record, reviewed by finance rather than the agent team. With volume flat, falling demand can’t explain the drop. What doesn’t survive: Tier 1 is our own classification, so the absolute figure can’t be compared across organizations.
Operator onboarding fell from 23 days to 3
The baseline isn’t attributable. The 23 days included time in a standing backlog, and part of the gain came from clearing that queue, not shortening the process. It shows a process re-engineered and a queue eliminated, not a like-for-like comparison.
Booking conversion rose 24%
The weakest of the three. A marketplace rebuild and opt-in dynamic pricing ran in the same window as the AI-native search capability credited with most of the uplift. Reported without that caveat, it would be the most impressive number here and the least informative.
Two of three carrying material qualifications is probably typical. A result that survives disclosure of its weaknesses is worth more than one never tested.
The failure that makes everything else moot
CLEAR assumes the operational record is complete. In agentic systems, one gap quietly breaks that assumption.
The most important control in our deployment cost nothing to build. Any line-of-business manager, from the wholesale desk to the cruise operations floor, could stop an agent within ninety seconds. No ticket, no approval. If the manager was wrong, we restarted the agent and discussed it at the next recalibration session. Being wrong cost an hour of throughput; being slow could cost a customer.
A manager using that control is the system working as designed. The failure is the override that isn’t logged. The record that would have shown a tolerance band was miscalibrated never exists, and the agent’s statistics are computed over a population from which a conscientious human has removed the hard cases.
Every downstream metric improves. Escalation rates fall because escalations were intercepted first. Confidence scores look strong because low-confidence decisions were pulled out by hand. Exception reports look clean. The organization believes its agents perform better than they do, and its results become unfalsifiable, because the basis was corrupted before anyone thought to write it down.
This echoes Lisanne Bainbridge’s 1983 “ironies of automation”: the human handles what the designer couldn’t automate, with no way to feed that judgment back into the design. No care at write-up time recovers a record that was never captured. Measurement in agentic systems is a daily operating discipline, not a reporting exercise.
Six practices that keep the record intact
We treated agents as high-volume junior team members: fast, tireless and capable of significant harm if poorly supervised. You wouldn’t put a new hire on the floor without onboarding and an escalation path, and agents are no different. Every manager with agents adopted six habits:
- A five-minute morning review of overnight agent activity, treated as a floor walk.
- A weekly scorecard written for operations, not technologists: completion, escalation rate, decision confidence.
- An exception-first culture that asks what the agent flagged as uncertain, not only what it did.
- Explicit human-agent teaming norms: when a human overrides, when they defer and how it’s logged.
- Scenario playbooks for the ten likeliest failure modes, owned by operations.
- A monthly recalibration session reviewing tolerance limits against incident data.
The fourth carries the most weight and gets the least attention. The sixth is how the organization learns, by asking what fired that shouldn’t have and what didn’t fire that should have. Both are answerable only if the override record is complete.
One design decision supports all six: we allocated autonomy by reversibility, not risk appetite. Non-technologists can classify reversibility at design time, and it maps straight to a control: the less reversible the action, the earlier a human must stand in the loop. Of our 25 agents, seven could act without confirmation. Thirteen either required it or were barred from autonomous external communication.
Where this won’t work
If you ship agent changes weekly, there’s no stable intervention to lock a window around; report rolling comparisons and say so. If the agent does work nobody did before, name the tests that don’t apply instead of quietly dropping them. Disclosure has commercial cost: we withheld volumes but disclosed the comparison basis. And disciplined reporters will look weaker than those who aren’t, a coordination problem no one practitioner can solve.
What to do on Monday
Check whether human overrides of agent decisions are logged. Inspect the log; don’t just ask whether one exists. If overrides aren’t captured, no performance figure you hold about your agents means what it appears to.
Then, before the next reporting cycle, lock your measurement window and write it down: the period, the denominator and everything else changing in the same interval. That costs nothing in advance and is impossible afterward. Then ask of every result: what would make a reader disbelieve this, and have I said so?
The organizations that scale agentic AI won’t have the best models; capability is converging and procurable. The operational habits around it aren’t, and they took us eighteen months to build. The technology was the easy part. The measurement was the work.